ReState

From Stages to States: Unified Iterative Reasoning for MLLMs

Chuang Yu1, Xuefei Ma2, Yuanhao Feng3, Wuxiong Zeng3, Bo Wang3, Minghong Cai1, Dongming Wu1, Fei Zhou1, Chen Tang1, Wenwen Tong4, Lewei Lu5, Xiangyu Yue1†

1MMLab, CUHK  ·  2PolyU  ·  3Tencent  ·  4Peking University  ·  5CPII

† Corresponding author

ReState = Reasoning-State Refinement

One modelUnifies reasoning construction, preservation, and correction within a single model.
10K CoTsVersaCoT-10K provides quality-controlled CoT annotations across 8 visual reasoning domains.
AdaptableA shared reasoning framework validated on Qwen2.5-VL, Qwen3-VL, and Qwen3.5 backbones.
StrongerOutperforms Direct SFT, Multimodal-CoT, and MIND on VersaCoT-10K, ScienceQA, and M³CoT.

TL;DR ReState is a unified iterative reasoning framework that reformulates multimodal reasoning from a stage-driven pipeline into a state-driven dynamic process.

01

Stage-centric vs. state-centric

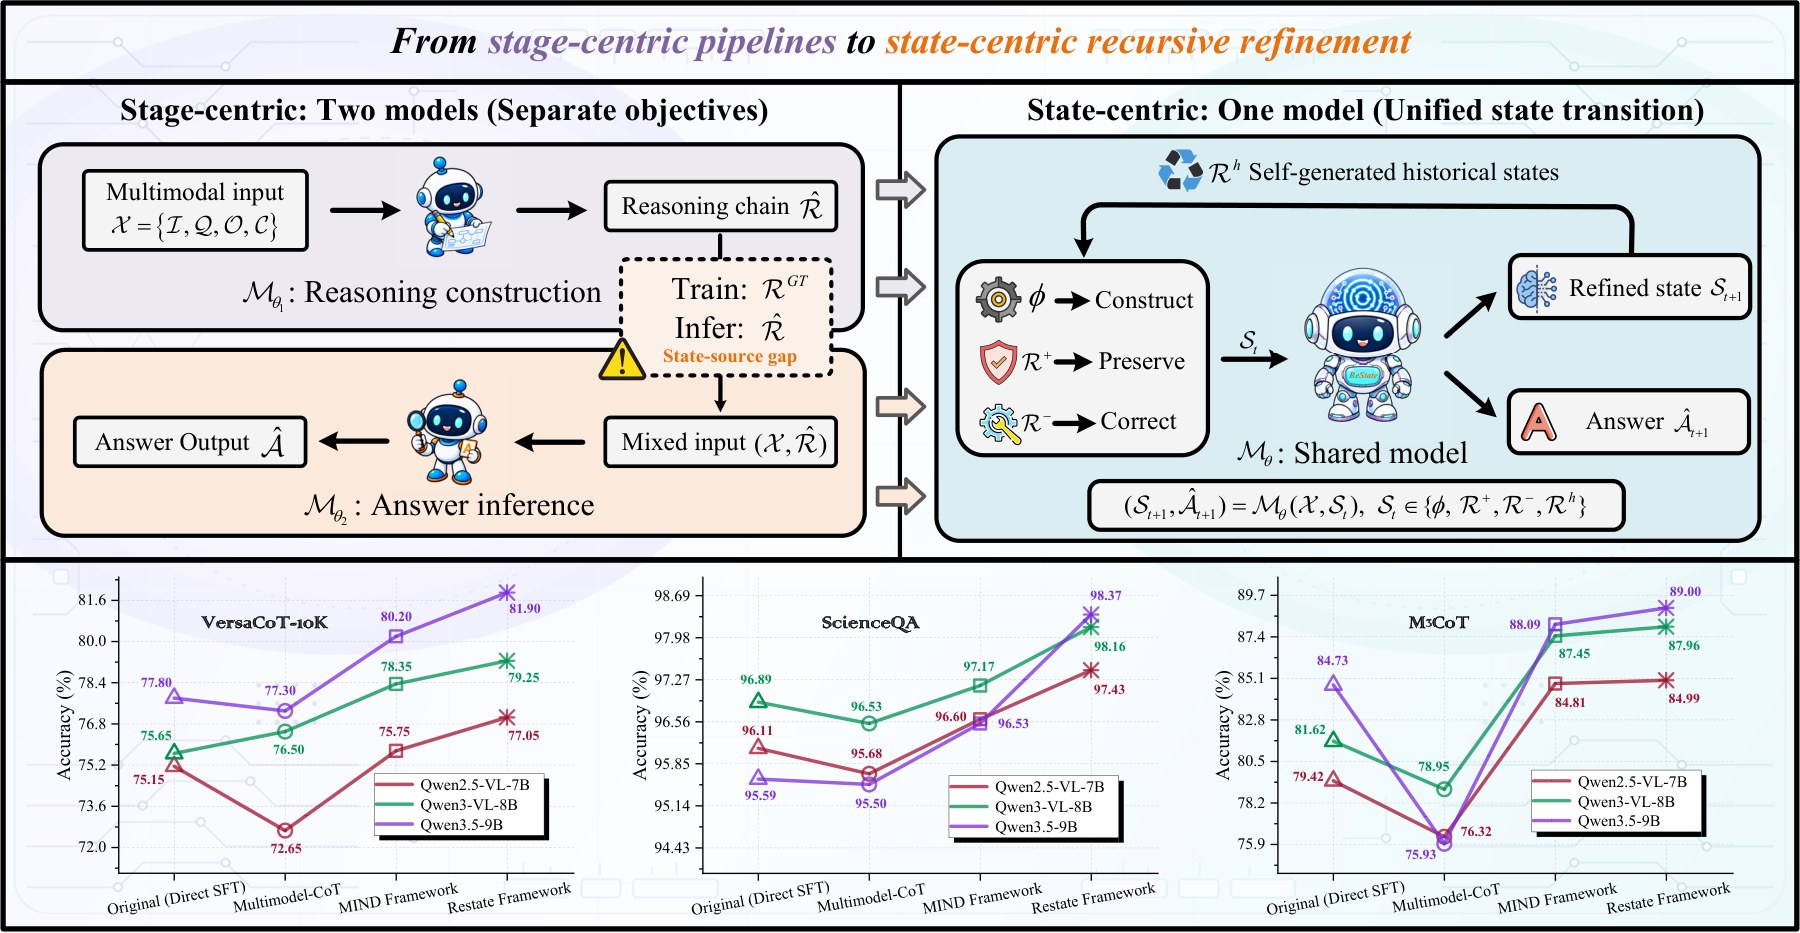
Most existing learning-based MCoT methods follow a stage-centric paradigm, assigning reasoning behaviors to predefined stages with separate optimization. This fragments reasoning and introduces a gap between the reasoning states used during training and those encountered at inference. ReState reformulates multimodal reasoning as a state-driven dynamic process, unifying reasoning construction, preservation, and correction through a shared state-update operator.

Multimodal input
X = {I, Q, O, C}
→
Mθ₁CoT generation
→
Reasoning chain
R̂
→
Mθ₂Answer inference
→
Answer Â
!
Fragmented reasoning. Construction, discrimination, and correction live in separate stages with separate objectives. There is no unified mechanism for how reasoning evolves.
!
Training–inference reasoning-state gap. Mθ₂ is trained on annotated chains RGT but receives model-generated chains R̂ at inference, so upstream errors propagate downstream.
Mixed input
(X, St)
→
Mθone shared state-update operator
→
Refined state St+1
Answer Ât+1
state feedback · St+1 becomes the next St
φ empty → construct R+ correct → preserve R− erroneous → correct Rh self-generated → refine
View original paper figure (Figure 1)
Figure 1: comparison of reasoning paradigms and performance
Figure 1. Stage-centric pipelines vs. state-centric recursive refinement, and accuracy across three backbones on VersaCoT-10K, ScienceQA and M³CoT.
02

Method: URSM + CRSL

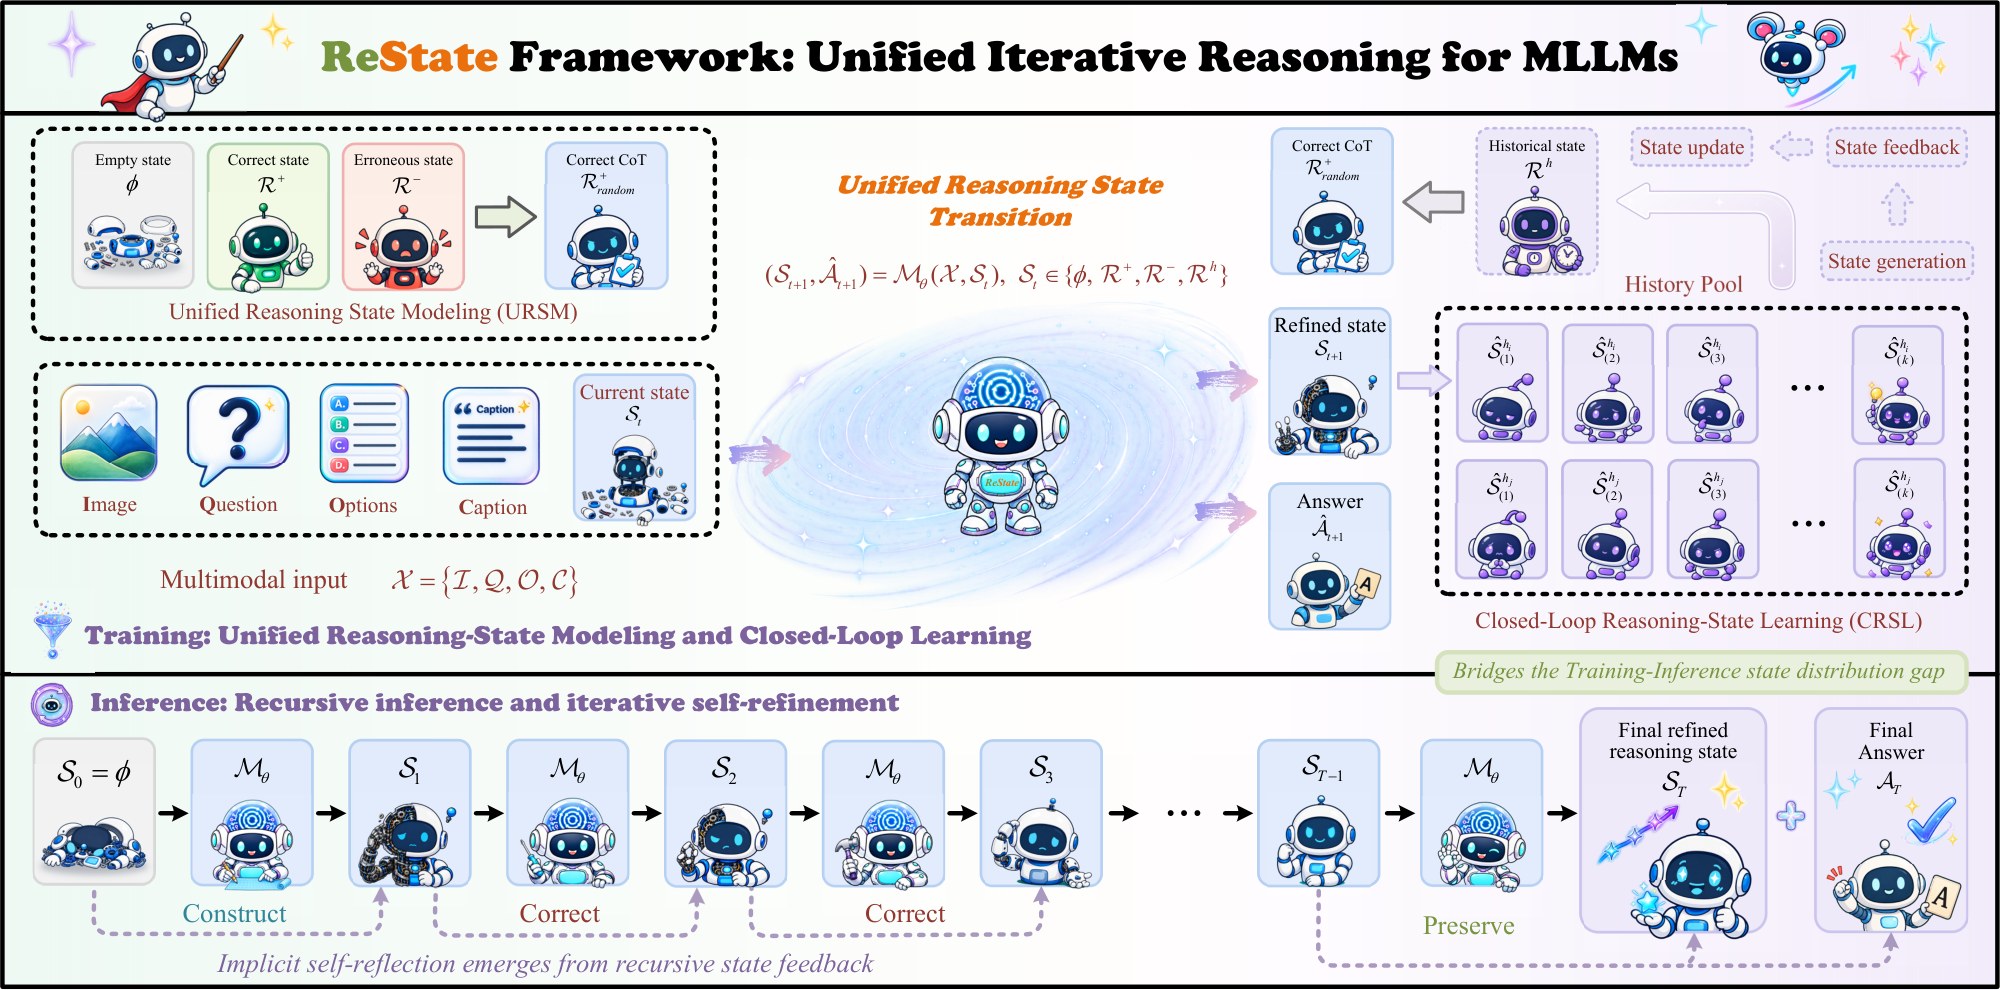
URSM unifies reasoning construction, correct reasoning preservation, and erroneous reasoning correction as state transitions learned jointly by a single MLLM. CRSL incorporates self-generated historical reasoning states during training and recursively updates the current state at inference, mitigating the training–inference reasoning-state gap and enabling iterative self-refinement without additional critics, reflection modules, or separate correction stages.

Unified Reasoning State Modeling

URSM: one operator, three behaviors

(St+1, Ât+1) = Mθ(X, St),   St ∈ {φ, R+, R−}

X = {image, question, options, caption}; φ is represented by the token [EMPTY_SOLUTION]. In each training epoch, URSM constructs two views per sample: one with φ and one with a non-empty reasoning state, sampled from either R+ or R− with equal probability.
Closed-Loop Reasoning-State Learning

CRSL: learning from self-generated states

Hi = {Ŝi(1), …, Ŝi(k)},   St ∈ {φ, R+, R−, Rh}
state generation→state feedback→state update↺
Per-sample history pool Hi · capacity 2 · FIFO
empty
empty

Each round, the state the model generates for sample i enters the pool and is reused as a training input Rh.

Inference: S0 = φ,   (St+1, Ât+1) = Mθ(X, St),   Â = ÂT
Figure 2: overview of the ReState framework
Figure 2. Overview of the ReState framework. During training, URSM learns a shared state-update operator from empty, correct, and erroneous reasoning states, while CRSL feeds model-generated historical states back into training to reduce the training-inference reasoning-state mismatch. At inference, the same model recursively updates the current reasoning state and answer, enabling iterative self-refinement without additional critics, reflection modules, or separate correction stages.
03

Watch a reasoning state evolve

Examples from VersaCoT-10K, ScienceQA, and M³CoT (Figs. 14–16) show how the same model revisits its previous reasoning state to correct errors, align answers with valid reasoning, and preserve successful updates. Step through the rounds to follow this process: red highlights reasoning errors, amber indicates a mismatch between reasoning and the selected answer, and green highlights corrected or preserved evidence.

04

VersaCoT-10K

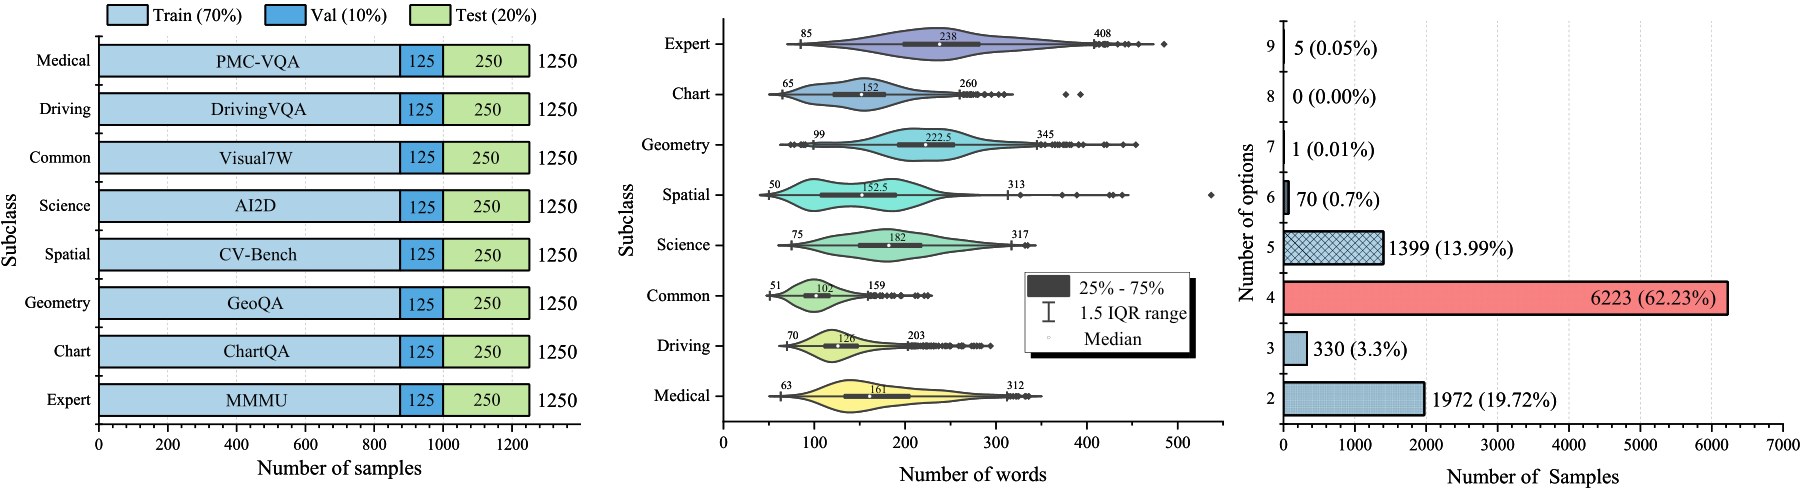
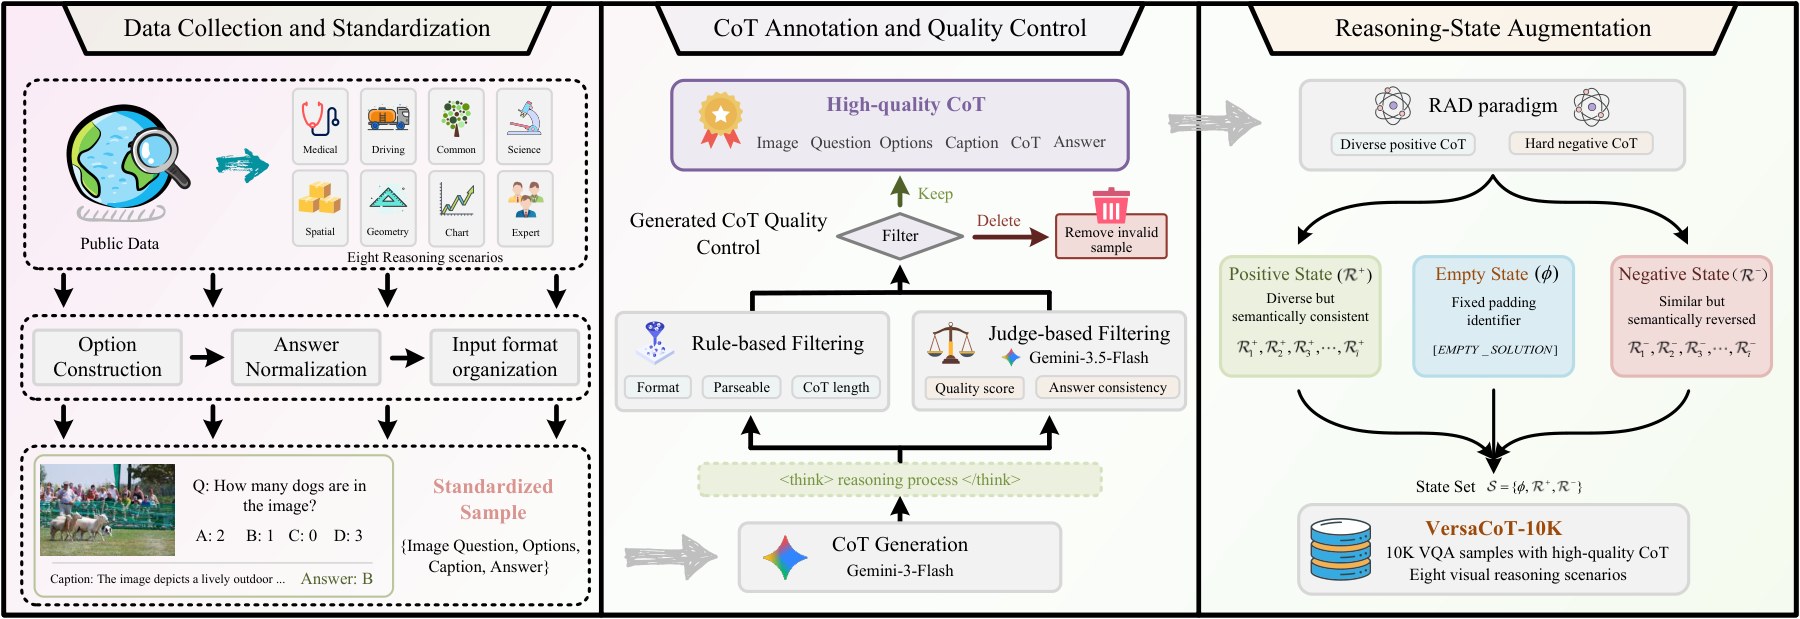
VersaCoT-10K contains 10,000 single-image multiple-choice samples spanning eight heterogeneous visual reasoning domains. Its construction consists of three stages: data collection and standardization, CoT annotation and quality control, and reasoning-state augmentation. The resulting dataset provides diverse supervision for multi-domain reasoning and reasoning-state refinement. Each domain contains 1,250 samples, with a 7 : 1 : 2 train / validation / test split.

10,000samples
8domains × 1,250
170.9avg CoT words (median 162, range 50–537)
2–9options per question
  1. 1Collect & standardize

    Reasoning-intensive samples from 8 public benchmarks, unified into one multiple-choice format with options, answer, and image caption.

  2. 2Annotate & filter

    Gemini-3-Flash writes visually grounded CoTs. Rule filters (200–4,000 chars, answer-leak phrases) plus a separate Gemini-3.5-Flash judge (all three binary checks must pass, and each of the five scores must be ≥ 8).

  3. 3Augment states

    Following RAD, each CoT gets positive states (diverse, semantically consistent) and hard negative states (similar, semantically reversed). Historical states Rh are generated online during training.

View dataset construction and statistics (Figures 3 & 7)
Figure 3: construction pipeline of VersaCoT-10K
Figure 3. Construction pipeline of VersaCoT-10K.
Figure 7: statistics of VersaCoT-10K
Figure 7. Sources and splits per domain, CoT length distribution, and option counts.
05

Results

Under matched backbone and training settings across three backbones, ReState outperforms Direct SFT, Multimodal-CoT, and MIND by 0.90%–4.60% on VersaCoT-10K, 0.83%–2.87% on ScienceQA, and 0.18%–13.07% on M³CoT.

Consistent improvements

Best average accuracy in all 9 matched-backbone settings across 3 datasets and 3 backbones. For example, on VersaCoT-10K with Qwen3.5-9B, average accuracy improves from 77.80% with Direct SFT to 81.90% with ReState.

Component ablation

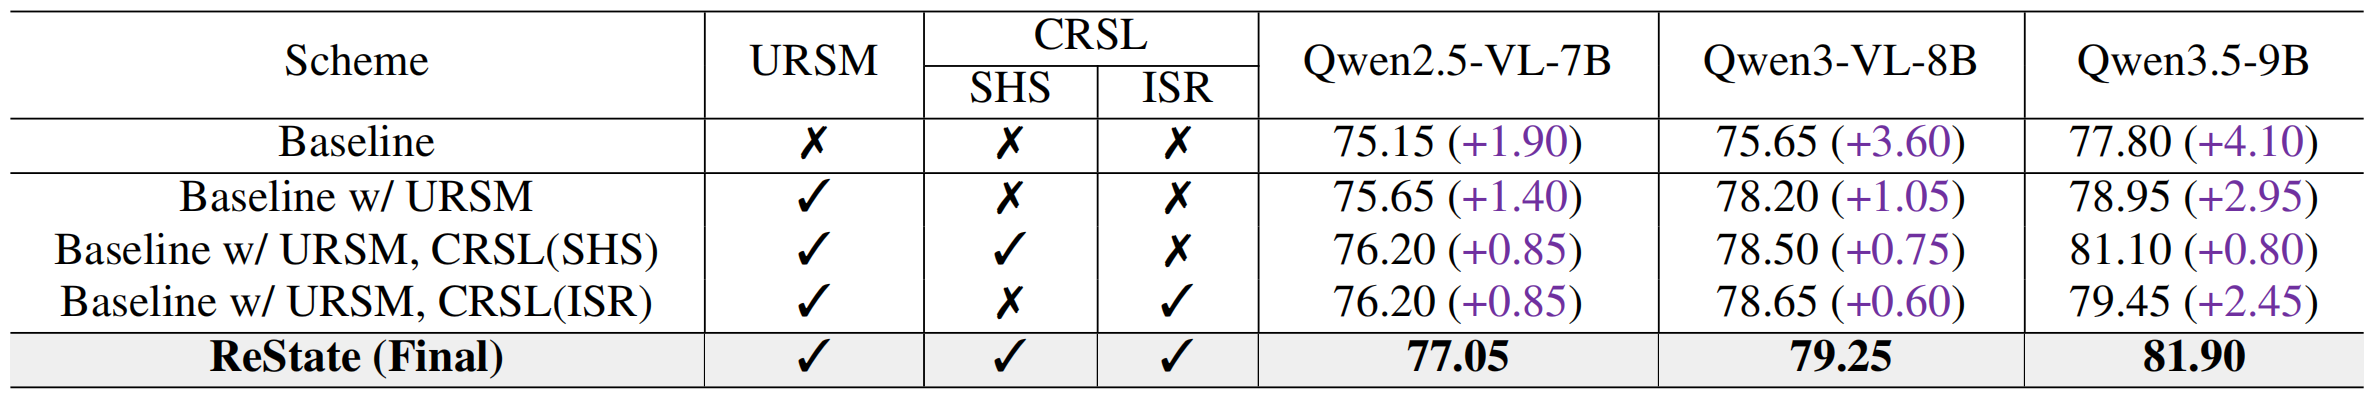
URSM improves accuracy by 0.50%–2.55% on VersaCoT-10K. Adding either training-time self-history states or inference-time iterative self-refinement brings further gains, with the full framework performing best across all three backbones.

Iterative refinement

One refinement round improves accuracy by 1.10%–2.65% on VersaCoT-10K. Most gains occur in the first few rounds, followed by stabilization with minor fluctuations.

Main results

Red = best, blue = second best, compared inside each 4-row backbone group. Highlighted rows are ReState.

Component Ablation and Iterative Refinement

On VersaCoT-10K, URSM improves accuracy by 0.50%–2.55% over Direct SFT. Adding SHS or ISR separately to URSM adds 0.30%–2.15% or 0.45%–0.55%, respectively. The full framework performs best across all three backbones, reaching 77.05%, 79.25%, and 81.90% on Qwen2.5-VL-7B, Qwen3-VL-8B, and Qwen3.5-9B, respectively.

Across VersaCoT-10K, ScienceQA, and M³CoT, iterative refinement delivers most of its gains in the first few rounds, after which accuracy stabilizes with minor fluctuations. The figures below summarize the component ablations and refinement trajectories.

View break-down ablation (VersaCoT-10K)
Table 4: ablation of URSM, self-history states, and iterative self-refinement on VersaCoT-10K across three backbones
Table 4. Break-down ablation on VersaCoT-10K. SHS = training-time self-history states; ISR = inference-time iterative self-refinement. Both are components of CRSL. Values in parentheses indicate the gap to full ReState.
View iterative refinement across three datasets (Figure 4)
Figure 4: accuracy over refinement rounds 0 to 9 on VersaCoT-10K, ScienceQA, and M³CoT across three backbones
Figure 4. Round 0 is the initial reasoning. One refinement round improves accuracy by 1.10%–2.65% on VersaCoT-10K, 0.04%–0.54% on ScienceQA, and 1.99%–3.62% on M³CoT. Most gains occur in the first few rounds, followed by stabilization with minor fluctuations.
06

Same question, four methods

Qualitative comparisons on VersaCoT-10K, ScienceQA, and M³CoT illustrate how visual evidence shapes reasoning outcomes. In these examples, Direct SFT, Multimodal-CoT, and MIND produce fluent reasoning but reach incorrect answers after misreading visual relationships, relying on misleading local cues, or introducing unsupported details. ReState identifies relevant evidence and integrates it into correct reasoning, from tracing diagram relationships and comparing concentrations to recognizing species and shapes. Click a card to view the full comparison (Figs. 8–13).

07

BibTeX

@article{yu2026stages,
  title={From Stages to States: Unified Iterative Reasoning for MLLMs},
  author={Yu, Chuang and Ma, Xuefei and Feng, Yuanhao and Zeng, Wuxiong and Wang, Bo and Cai, Minghong and Wu, Dongming and Zhou, Fei and Tang, Chen and Tong, Wenwen and others},
  journal={arXiv preprint arXiv:2610.15620},
  year={2026}
}